A2P SMS Traffic Overflow: An Operational Guide
How to assess an alternative route during a temporary capacity shortfall, limit rerouting, and record decisions without confusing a DLR with confirmed receipt on a handset.
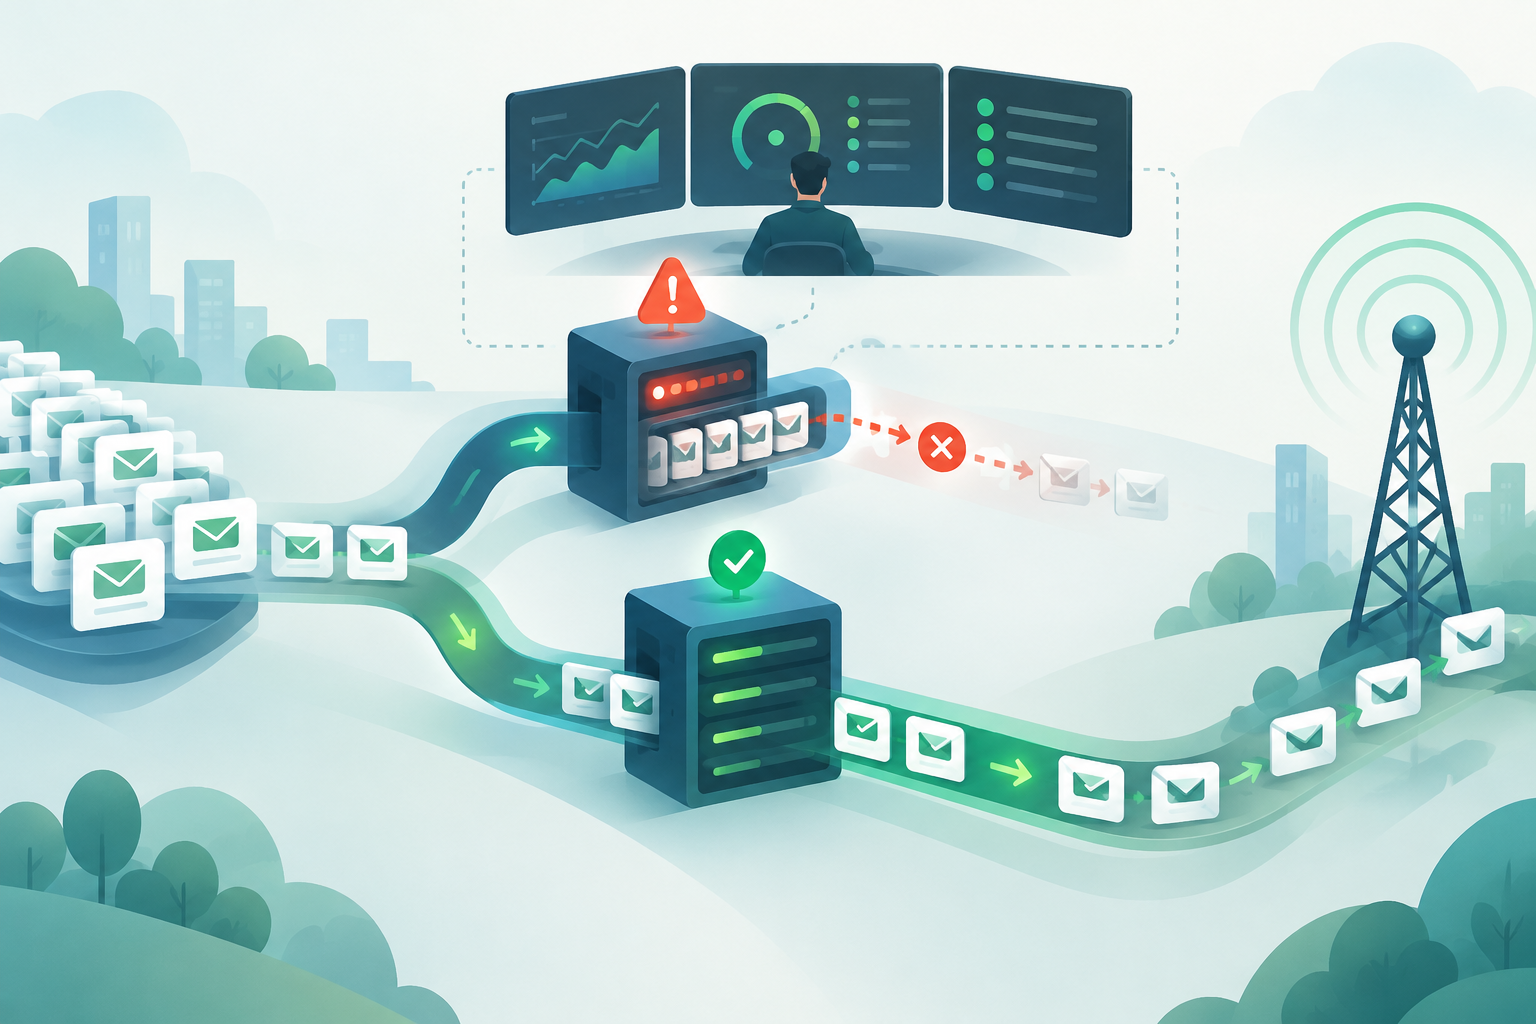
What traffic overflow does—and does not—solve
Traffic overflow is a policy for distributing or admitting some traffic through an alternative route when the available capacity on the primary route is insufficient. Its purpose is to manage a temporary shortfall; it does not automatically make an alternative route equivalent, nor does it prove that a message reached the handset.
It is useful to distinguish overflow from other mechanisms. Failover usually describes switching when a route becomes unavailable. Fallback means using an alternative when a defined operation or condition fails. Backpressure limits or holds incoming traffic to avoid overloading a system. TPS planning aims to size demand and capacity in advance. These terms may overlap in an implementation, so the team should document the condition that triggers each action.
- Before rerouting traffic, define whether the cause is insufficient capacity, unavailability, a connectivity failure, or another error.
- Do not treat all rejections as congestion: interpret an error code or message according to the documentation agreed with each connection.
- Traffic overflow does not fix issues with permissions, sender, content, destination, or configuration.
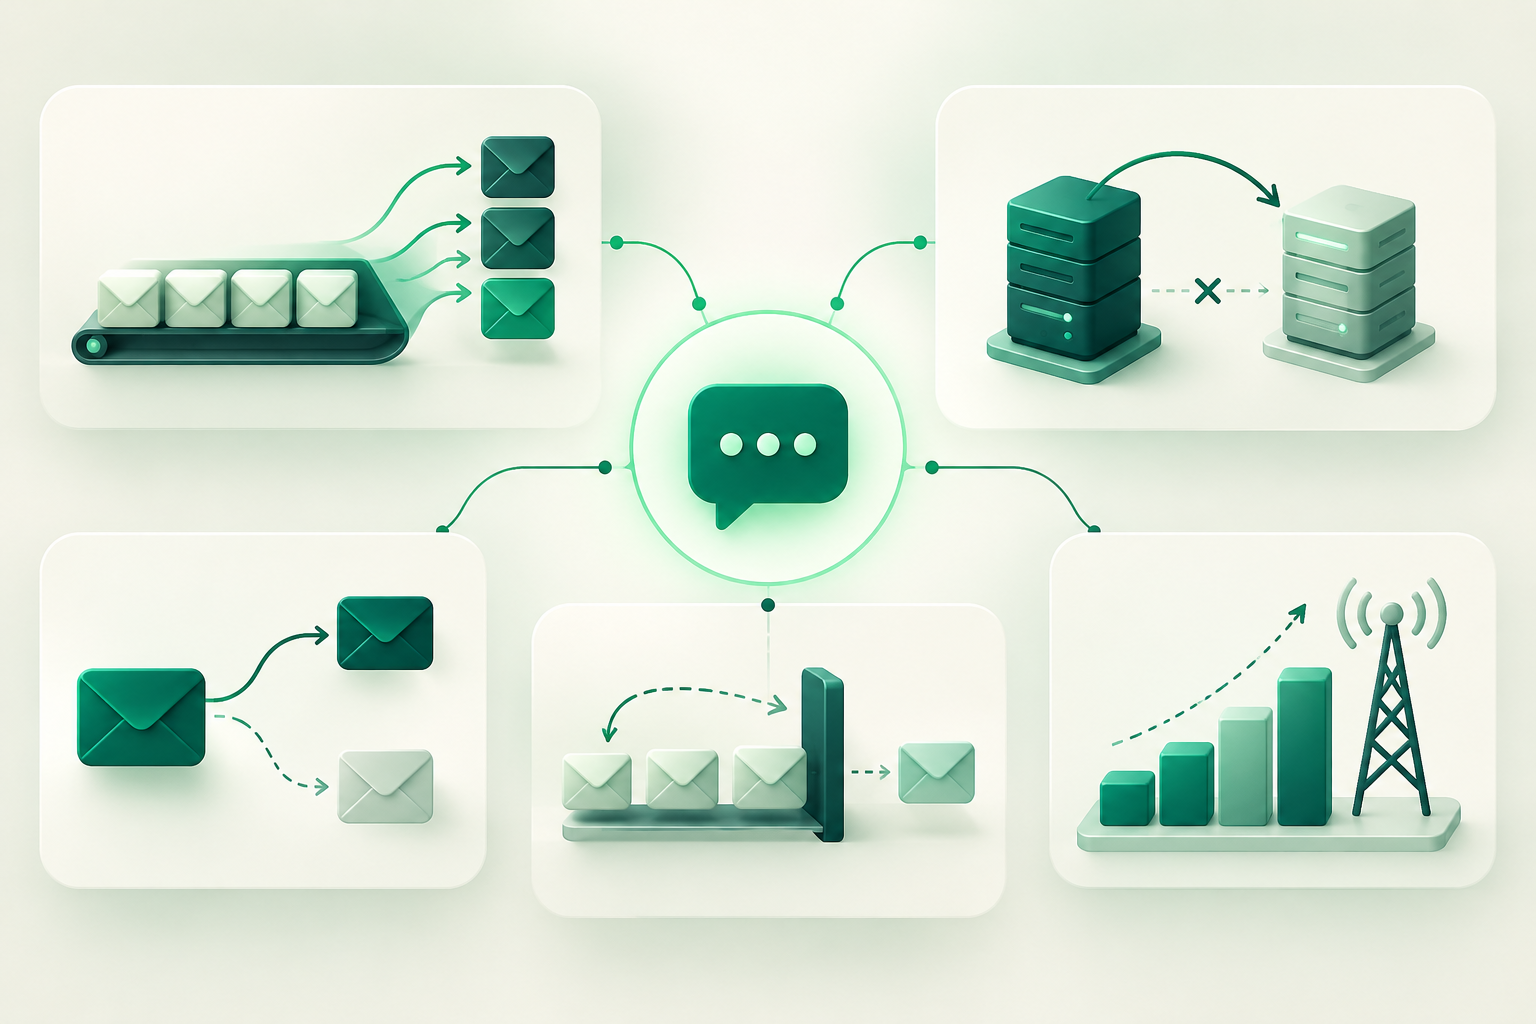
Confirm the signal before rerouting
The available evidence does not establish a universal list of rejection codes that distinguishes congestion from other failures. The first operational task is therefore to agree with each provider or connection on how capacity-related rejections are represented and which other errors may look similar.
Examine the signal alongside its context: offered volume, connection responses, queue size and trend, observed availability, and confirmed capacity on the alternative route. A growing queue may indicate pressure, but by itself it does not prove that the route is the cause. If the cause remains ambiguous, limit or pause sending in line with your internal policy rather than assuming rerouting will solve the problem.
- Preserve the original response and its timestamp; do not reduce it to a generic category without retaining the detail.
- Check that the alternative route has confirmed capacity for the destination and traffic type before admitting load.
- Separate capacity failures from formatting, authorization, sender, connectivity, and destination errors where the connection documentation allows.
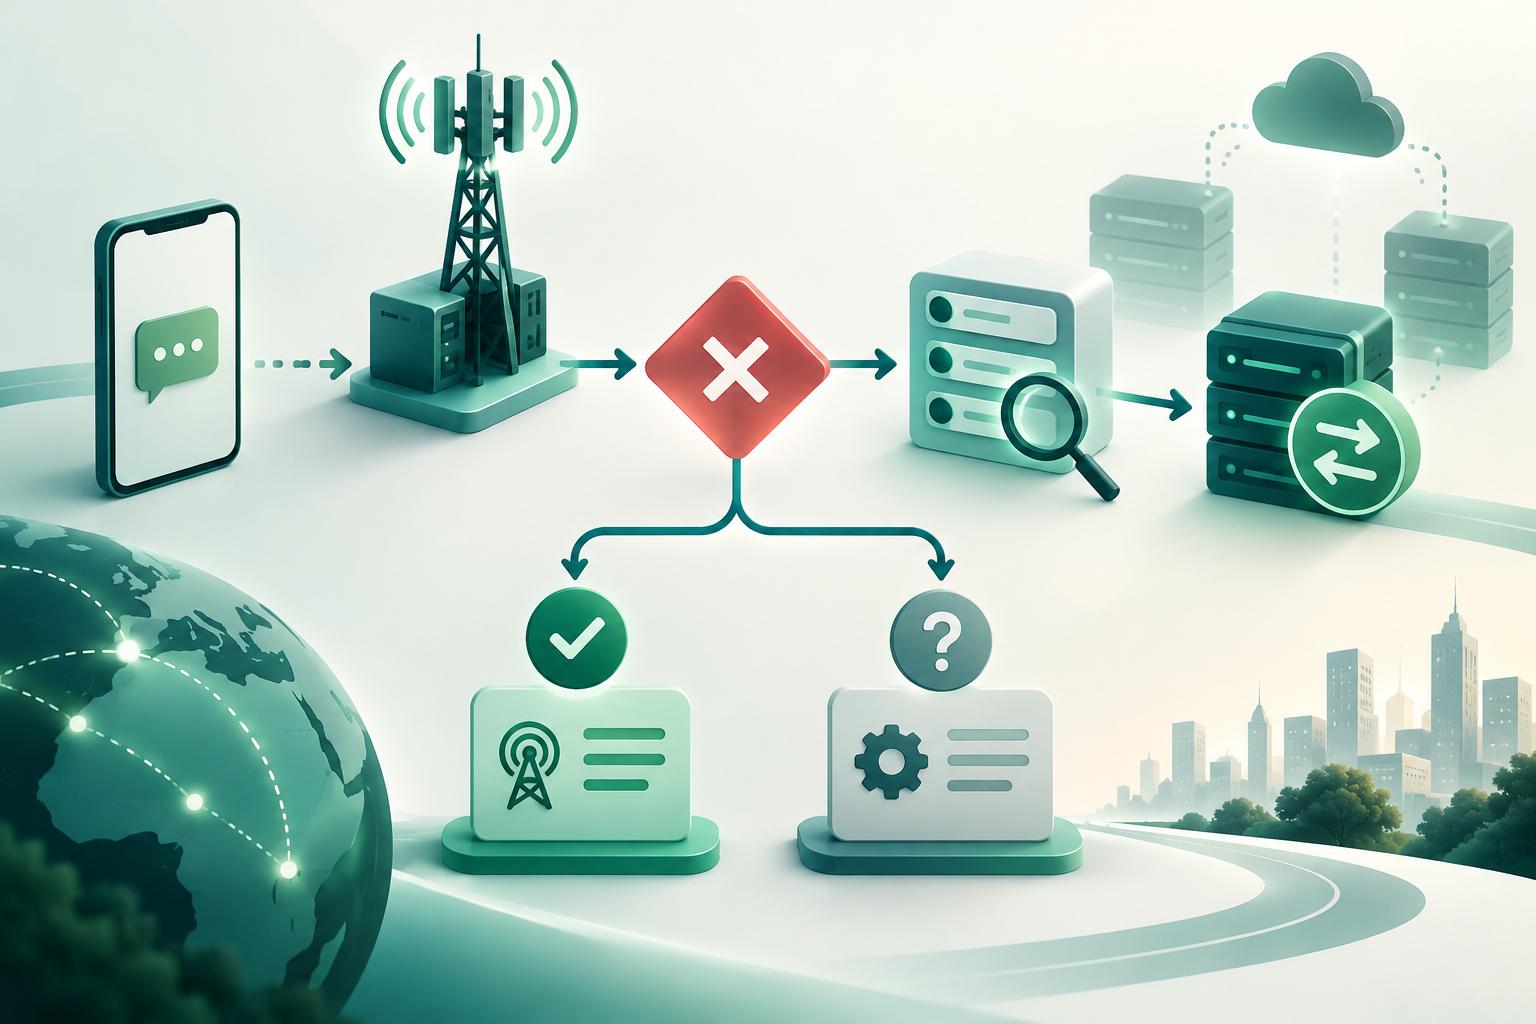
Define eligibility before activating the route
The alternative route must be authorized for the specific traffic. Before using it, verify the destination, sender, content, and message class against applicable agreements and current rules. Do not assume that a route available for one country, operator, or traffic type automatically supports others.
Technical availability also does not establish that a message is permitted or that consent exists. Traffic overflow must preserve the compliance, consent, and preference controls applied on the primary route.
- Document the destinations and senders supported by each alternative using current contractual or technical information.
- Confirm that the content and traffic class are compatible with the connection and applicable rules.
- If eligibility is not evidenced, exclude that traffic from the overflow policy until it has been verified.
Set thresholds and limits without inventing standard values
No universal threshold for activating traffic overflow is supported here. Set values using your own data, agreed capacity, and operational objectives. Define which metric triggers the decision—for example, confirmed capacity-related rejections or queue trends—the observation window used, and who may adjust the policy.
Hysteresis helps prevent repeated switching between routes when a metric fluctuates near a threshold: you can define one condition for starting rerouting and a separate one for stopping it. This is a design principle, not a prescribed value. There should also be volume or rate limits to prevent the alternative from receiving more traffic than its confirmed capacity can handle.
- Choose observation windows based on measured behavior and the latency of available signals.
- Set explicit limits for each route and, where appropriate, each destination or traffic class; do not exceed confirmed capacity.
- Define separate conditions for starting and stopping rerouting, as well as the person or team responsible for the decision.
- Review limits after changes to capacity, configuration, or agreements; do not present internal parameters as industry standards.
Avoid duplicates when the outcome is uncertain
If a message sent on the primary route has an uncertain status, resending it through another route may result in a second delivery. The available evidence does not establish a universal rule for preventing duplicates or indicate that all connections share the same status semantics.
Define an explicit policy for ambiguous statuses and base it on the connection documentation. Before resending, record what is known and what is not. Do not interpret the absence of a DLR as proof that the message was not delivered, and do not assume that connection acceptance is equivalent to delivery.
- Distinguish between rejected, accepted by the connection, pending, and unknown outcomes where the interface allows.
- Agree with route owners on how to handle each status before automating retries or rerouting.
- If you cannot determine the prior outcome, apply a conservative policy that avoids unjustified automatic resends.
Monitor the alternative and interpret DLRs cautiously
During overflow, compare the volume offered with the volume accepted by each connection, and monitor rejections, queues, available latency measurements, and reported statuses. Review results by destination and traffic class to detect concentrated problems and avoid an aggregate signal hiding a specific failure.
A DLR is a status reported by the delivery chain. On its own, it should not be treated as independent proof that the message was received on the handset. Retain the status definition provided by the connection and distinguish what the system reports from what can be independently verified.
- Record offered, accepted, and rejected volumes by route, along with available statuses and timestamps.
- Track observed latency and availability without turning a single measurement into a future guarantee.
- Compare the primary and alternative routes using consistent criteria, broken down by destination where the data allows.
Stop, return to the primary route, and escalate
The conditions for ending overflow should also be defined in advance. Establish what evidence indicates that the primary route has recovered capacity, how long that condition must persist according to your observation window, and how to avoid returning too early. No universal values for these parameters are provided.
Stop or reduce rerouting if the alternative reaches its limit, shows signs of degradation, or is no longer eligible for the traffic. Escalate when the cause, capacity, or message status cannot be confirmed, and keep traffic within existing operational and compliance controls.
- Use exit conditions that differ from entry conditions to reduce route oscillation.
- Ensure the return to the primary route is gradual or controlled according to confirmed capacity and system design.
- Escalate according to predefined responsibilities and agreements; do not assume a route change will solve a failure with an unknown cause.
Keep an auditable record
A useful record makes it possible to reconstruct what was observed, why the decision was made, and what happened next. The available evidence does not specify mandatory fields, so each organization should define them according to its operational, compliance, and retention needs.
As a practical baseline, link the decision to the observation period, affected route, relevant destination or traffic group, signals reviewed, limit applied, person or system that authorized the action, and activation and stop times. Also retain available responses and statuses, distinguishing reported data from verified facts.
- Retain the assigned cause and the supporting evidence, including the original technical response where possible.
- Record how much traffic was rerouted and the observed outcomes without turning them into a delivery guarantee.
- Note manual changes, exceptions, escalations, and the reasons for retrying or not resending messages with uncertain outcomes.
- Review the record after the incident and adjust the policy using your own data and confirmed capacity.
Frequently asked questions
When should A2P SMS traffic overflow be activated?
When signals support an interpretation of insufficient capacity and the alternative route has confirmed capacity and eligibility. If the cause of a rejection is uncertain, do not automatically classify it as congestion.
What overflow threshold should be used?
No universal value is supported here. Define one using your own data, agreed capacity, observation windows, and a distinct stop condition; always limit traffic to the alternative route’s confirmed capacity.
Does a DLR confirm that an SMS reached the phone?
A DLR should not, by itself, be treated as independent proof of receipt on the handset. Interpret the status according to the semantics provided by the connection and distinguish it from independent verification.
Should an SMS with an uncertain outcome be resent through another route?
Not automatically without an agreed policy: resending can create duplicates, and the absence of a conclusive status does not prove that the first attempt was not delivered. Check the connection’s status semantics and record the decision.
Does BulkSMSMarket currently offer automatic traffic overflow in production?
The available information describes a platform in development for discovering, comparing, buying, selling, and managing A2P SMS capacity, as well as HTTP and SMPP connectivity and HLR lookups. The public live-routing backend is not yet available; automatic traffic overflow should not be assumed to be an active feature.
Sources consulted
- 3GPP specifications3GPP
- ITU-T E.164International Telecommunication Union
- GSMA resourcesGSMA